Monitors do not send notifications yet. Each run is checked against your thresholds and marked OK or Alert in the monitor’s run history. On Datafold Classic, see Data Diff Monitors for alerting options.
Ways to create a data diff monitor
There are 3 ways to create a data diff monitor:- From the Monitors page, click Create new monitor.
- Clone an existing monitor: open Actions and select Clone. This pre-fills the form with the existing monitor configuration.
- Define it in YAML with monitors as code.
Create a new data diff monitor
Setting up a new diff monitor in Datafold is straightforward. You can configure it with the following parameters and options:General
Choose how you want to compare your data and whether the diff type is in-database or cross-database. Pick your data connections. Then, choose the two datasets you want to compare. This can be a table or a view in your relational database. If you need to compare just a subset of data (e.g., for a particular city or last two weeks), add a SQL filter. For cross-database monitors, select Materialize inputs to improve diffing speed when query is heavy on compute, or if filters are applied to non-indexed columns, or if primary keys are transformed using concatenation, coalesce, or another function.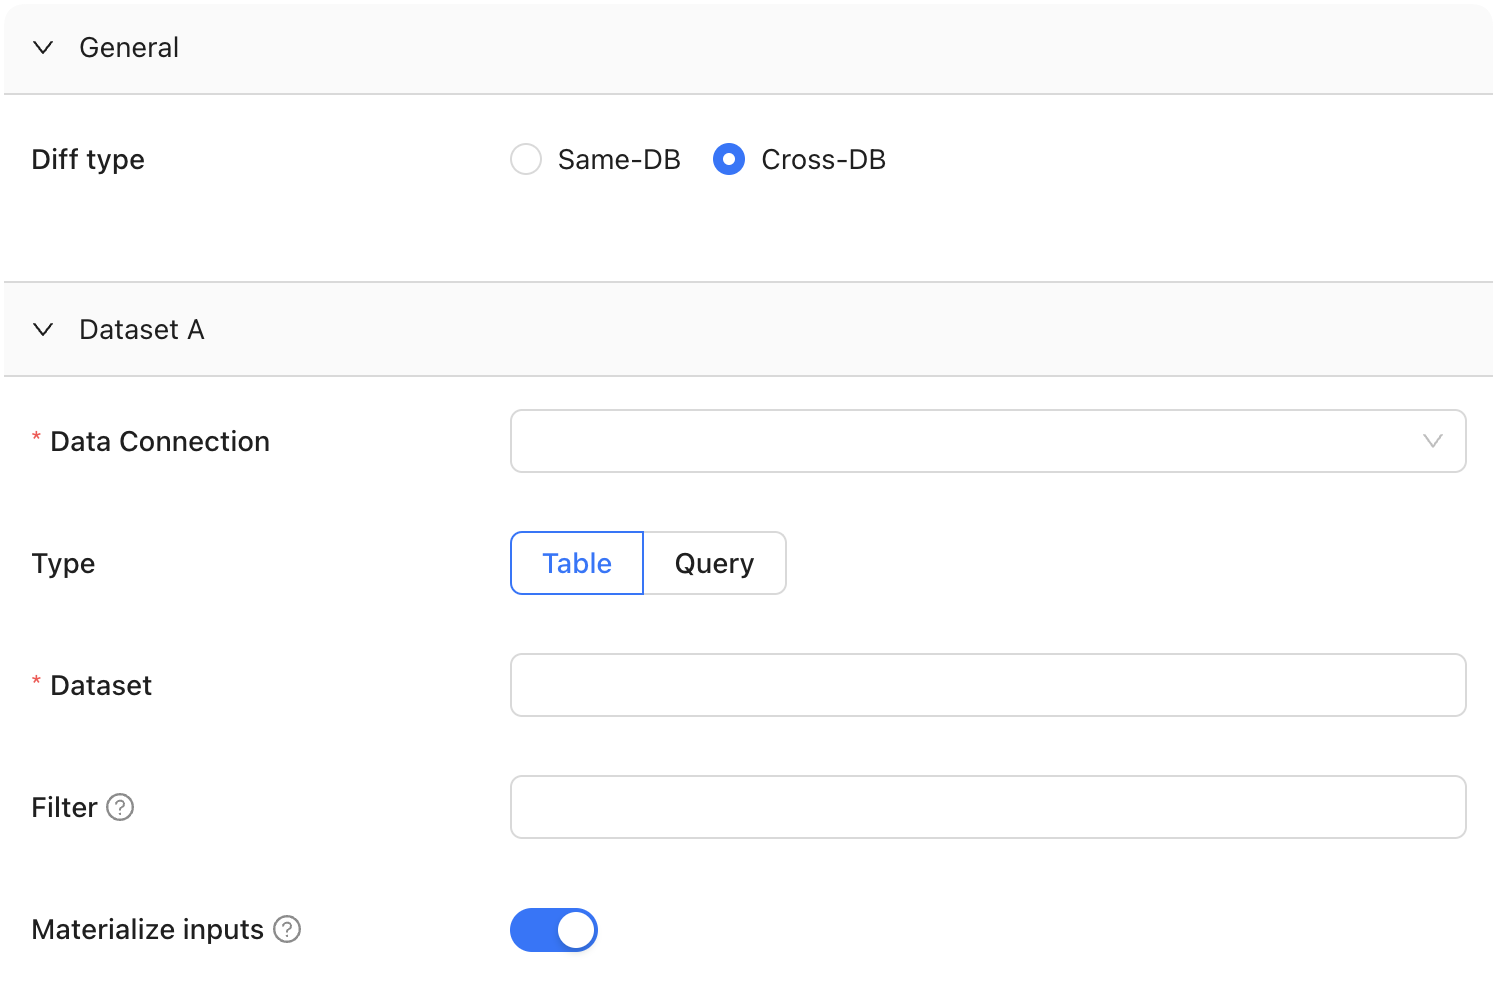
Data Diff General Settings
Column remapping
When columns are the same data type but are named differently, column remapping allows you to align and compare them. This is useful when datasets have semantically identical columns with different names, such asuserID and user_id. Datafold will surface any differences under the column name used in Dataset A.
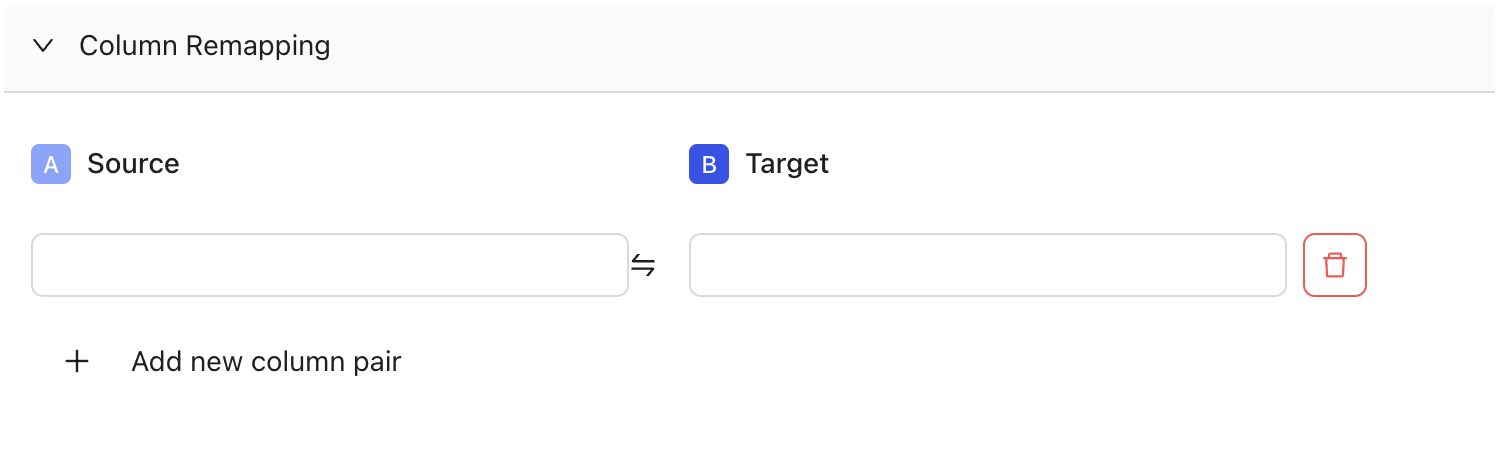
Column Remapping Settings
Diff settings
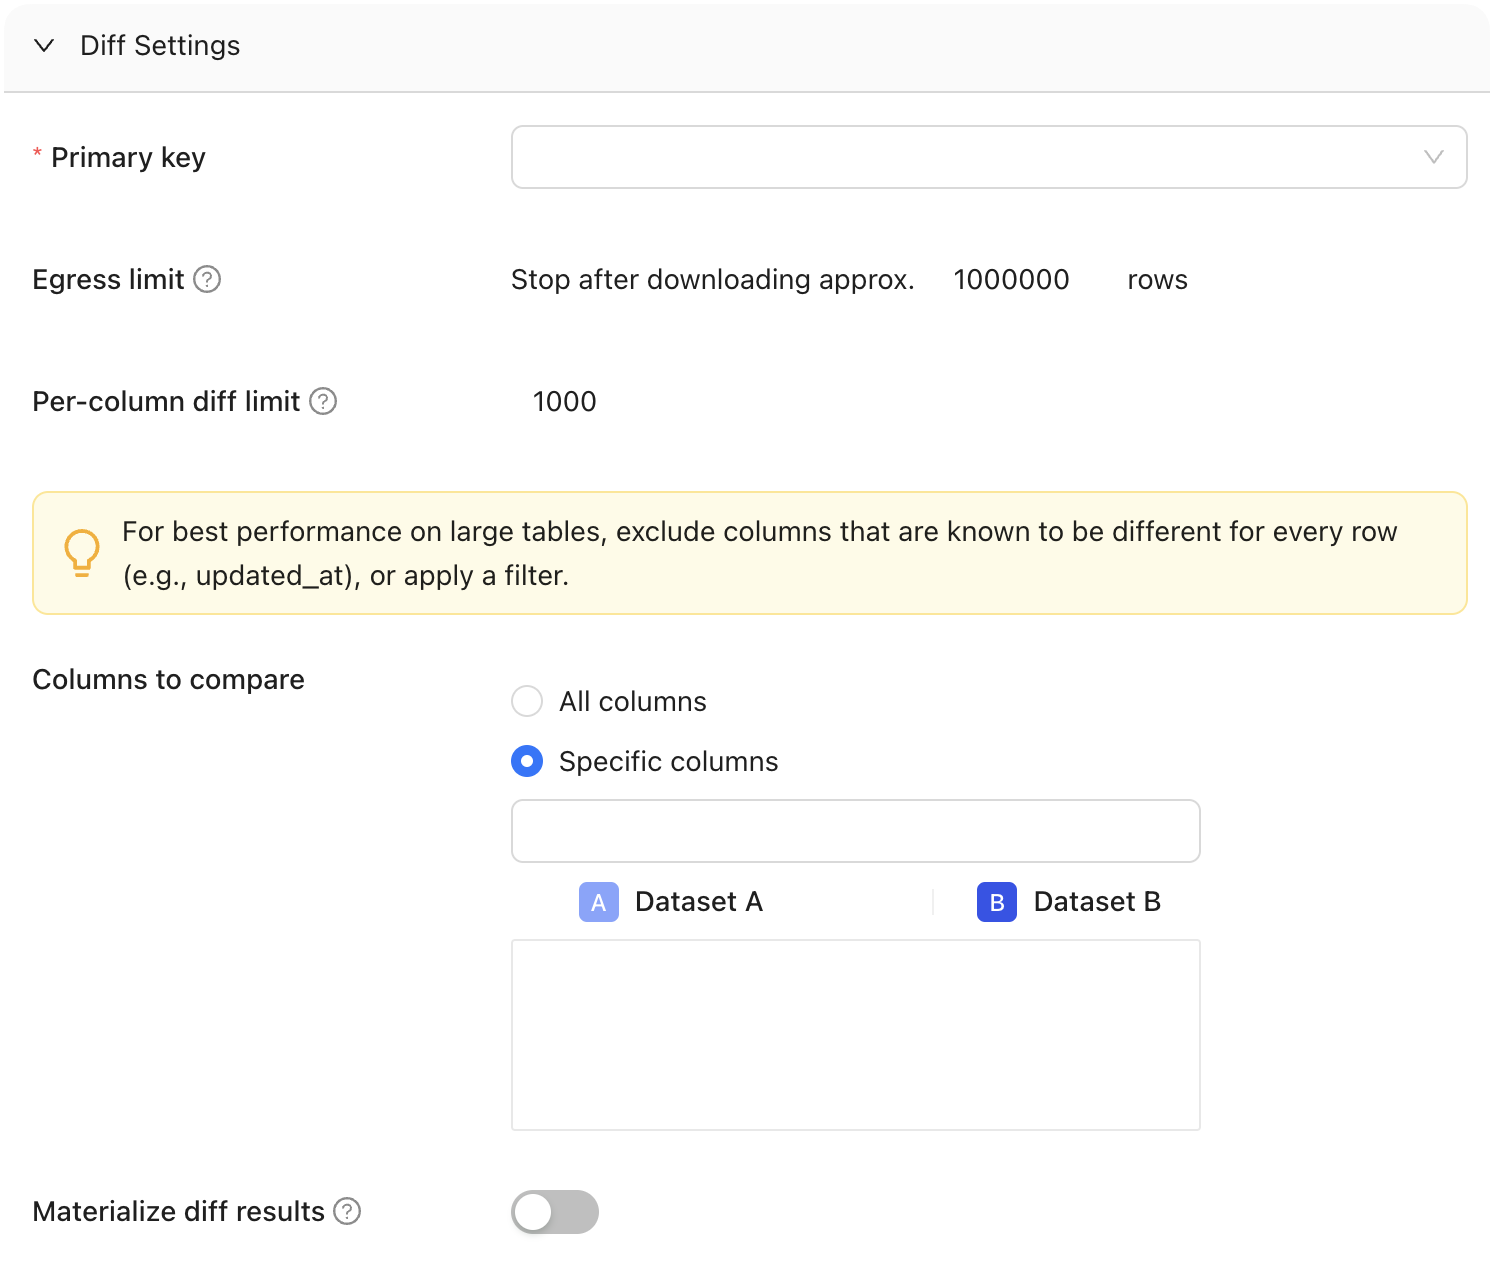
Diff Settings
Primary key
The primary key is one or more columns used to uniquely identify a row in the dataset during diffing. The primary key (or keys) does not need to be formally defined in the database or elsewhere as it is used for unique row identification during diffing. Multiple columns support compound primary key definitions.Columns to compare
Determine whether to compare all columns or select specific one(s). To optimize performance on large tables, it’s recommended to exclude columns known to have unique values for every row, such as timestamp columns like “updated_at,” or apply filters to limit the comparison scope.Materialize diff results
Choose whether to store diff results in a table.Sampling
Use this to compare a subset of your data instead of the entire dataset. This is best for assessing large datasets. There are three ways to enable sampling: Tolerance, % of Rows, and Max Rows (sample approximately N rows, or the whole table if it is smaller).Tolerance
Tolerance defines the allowable margin of error for our estimate. It sets the acceptable percentage of rows with primary key errors (like nulls, duplicates, or primary keys exclusive to one dataset) before disabling sampling.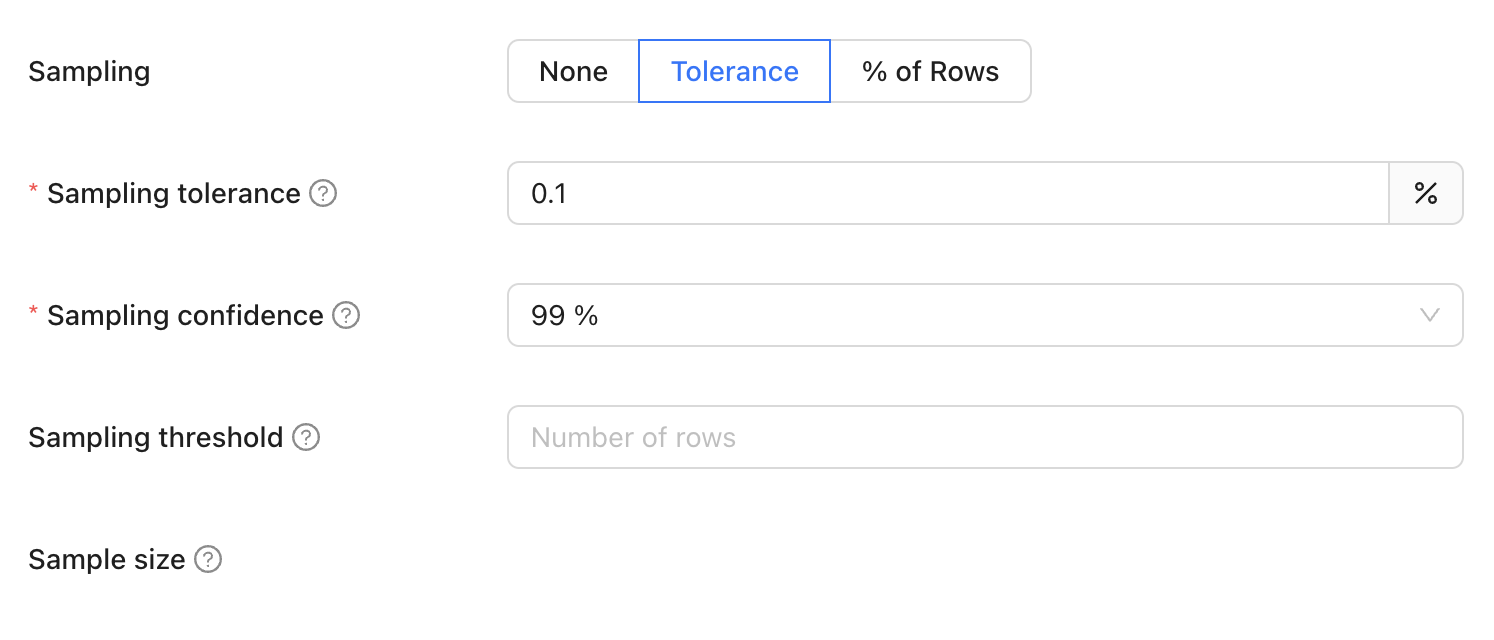
Sampling confidence
Sampling confidence reflects our level of certainty that our sample accurately represents the entire dataset. It represents the minimum confidence level that the rate of primary key errors is below the threshold defined in sampling tolerance. To put it simply, a 95% confidence level with a 5% tolerance means we are 95% certain that the true value falls within 5% of our estimate. Default: 99%Sampling threshold
Sampling will be disabled if total row count of the largest table is less than the threshold value.Sample size
This provides an estimated count of the total number of rows included in the combined sample from Datasets A and B, used for the diffing process. It’s important to note that this number is an estimate and can vary from the actual sample size due to several factors:- The presence of duplicate primary keys in the datasets will likely increase this estimate, as it inflates the perceived uniqueness of rows
- Applying filters to the datasets tends to reduce the estimate, as it narrows down the data scope
- Sampling tolerance: 5%
- Sampling confidence: 95%
% of rows
Percent of rows sampling defines the proportion of the dataset to be included in the sample by specifying a percentage of the total number of rows. For example, setting the sampling percentage to 0.1% means that only 0.1% of the total rows will be sampled for analysis or comparison.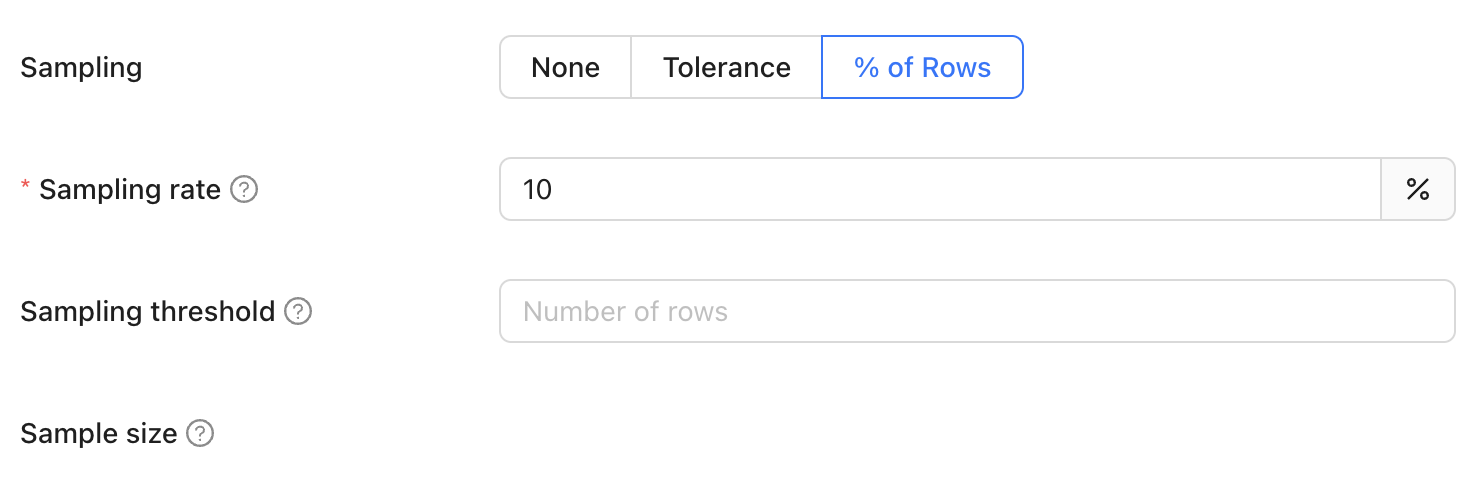
Sampling rate
This refers to the percentage of the total number of rows in the largest table that will be used to determine the sample size. This ensures that the sample size is proportionate to the size of the dataset, providing a representative subset for comparison. For instance, if the largest table contains 1,000,000 rows and the sampling rate is set to 1%, the sample size will be 10,000 rows.Sampling threshold
Sampling is automatically disabled when the total row count of the largest table in the comparison falls below a specified threshold value. This approach is adopted because, for smaller datasets, a complete dataset comparison is not only more feasible but also quicker and more efficient than sampling. Disabling sampling in these scenarios ensures comprehensive data coverage and provides more accurate insights, as it becomes practical to examine every row in the dataset without significant time or resource constraints.Sample size
This parameter is the same one used in sampling tolerance.Monitor details
Give the monitor a Name, and optionally a Description, Tags, and an Owner. The Identifier is a stable key of lower-case letters, digits, dashes, and underscores. Monitors as code matches monitors by this identifier, so a monitor without one cannot be exported to YAML.Add a schedule
Choose Hourly, Daily, or Custom (a five-field cron expression in UTC). The minimum gap between runs is one hour. Choose None to run the monitor only when you start it by hand or through the API. Datafold picks the exact minute inside the hour or day for each monitor, so many monitors don’t all start at the same time.Set thresholds
A run is marked Alert when it crosses any threshold you set. Leave a value blank to not check it.- Number of different rows: alert when a run finds more differing rows than this (rows with different values plus rows present on only one side).
- Percentage of different rows: alert when the share of differing rows is above this percentage.
- Match score: alert when the run’s Match Score is below this percentage.
Results
Each monitor has a Settings tab and a History tab. The run history shows the result of each run:- Status: Created, Checking (running), OK, Alert, Error, or Cancelled.
- Match score, row counts for each table, Total rows different, Rows with different values, and rows exclusive to each dataset.
- Thresholds exceeded: which thresholds caused an Alert.
- Source: whether the run was scheduled or started by hand.
Monitors managed in code
A monitor created from YAML shows the banner This monitor is managed in code. Change it by editing the YAML and provisioning it again. It can’t be edited or deleted in the app; to stop it, setenabled: false in the YAML.
To get the YAML for any monitor, open Actions and select View as Code.
Permissions
Monitor access is controlled by three permissions: View monitors, Run monitors, and Edit monitors. See User roles and permissions.FAQ
Sampling tolerance vs. % of rows
Sampling tolerance vs. % of rows
Use sampling tolerance when you need statistical confidence in your results, as it is more efficient and stops sampling once a difference is confidently detected. This method is ideal for critical data validation tasks that require precise accuracy.On the other hand, use the percent of rows method for its simplicity and ease of use, especially in less critical scenarios where you just need a straightforward, quick sampling approach without worrying about statistical parameters. This method is perfect for general, easy-to-understand sampling needs.
Need help?
Need help?
If you have any questions about how to use Data Diff monitors, please reach out to our team via Slack, in-app chat, or email us at support@datafold.com.